Protocol design
Device Registration
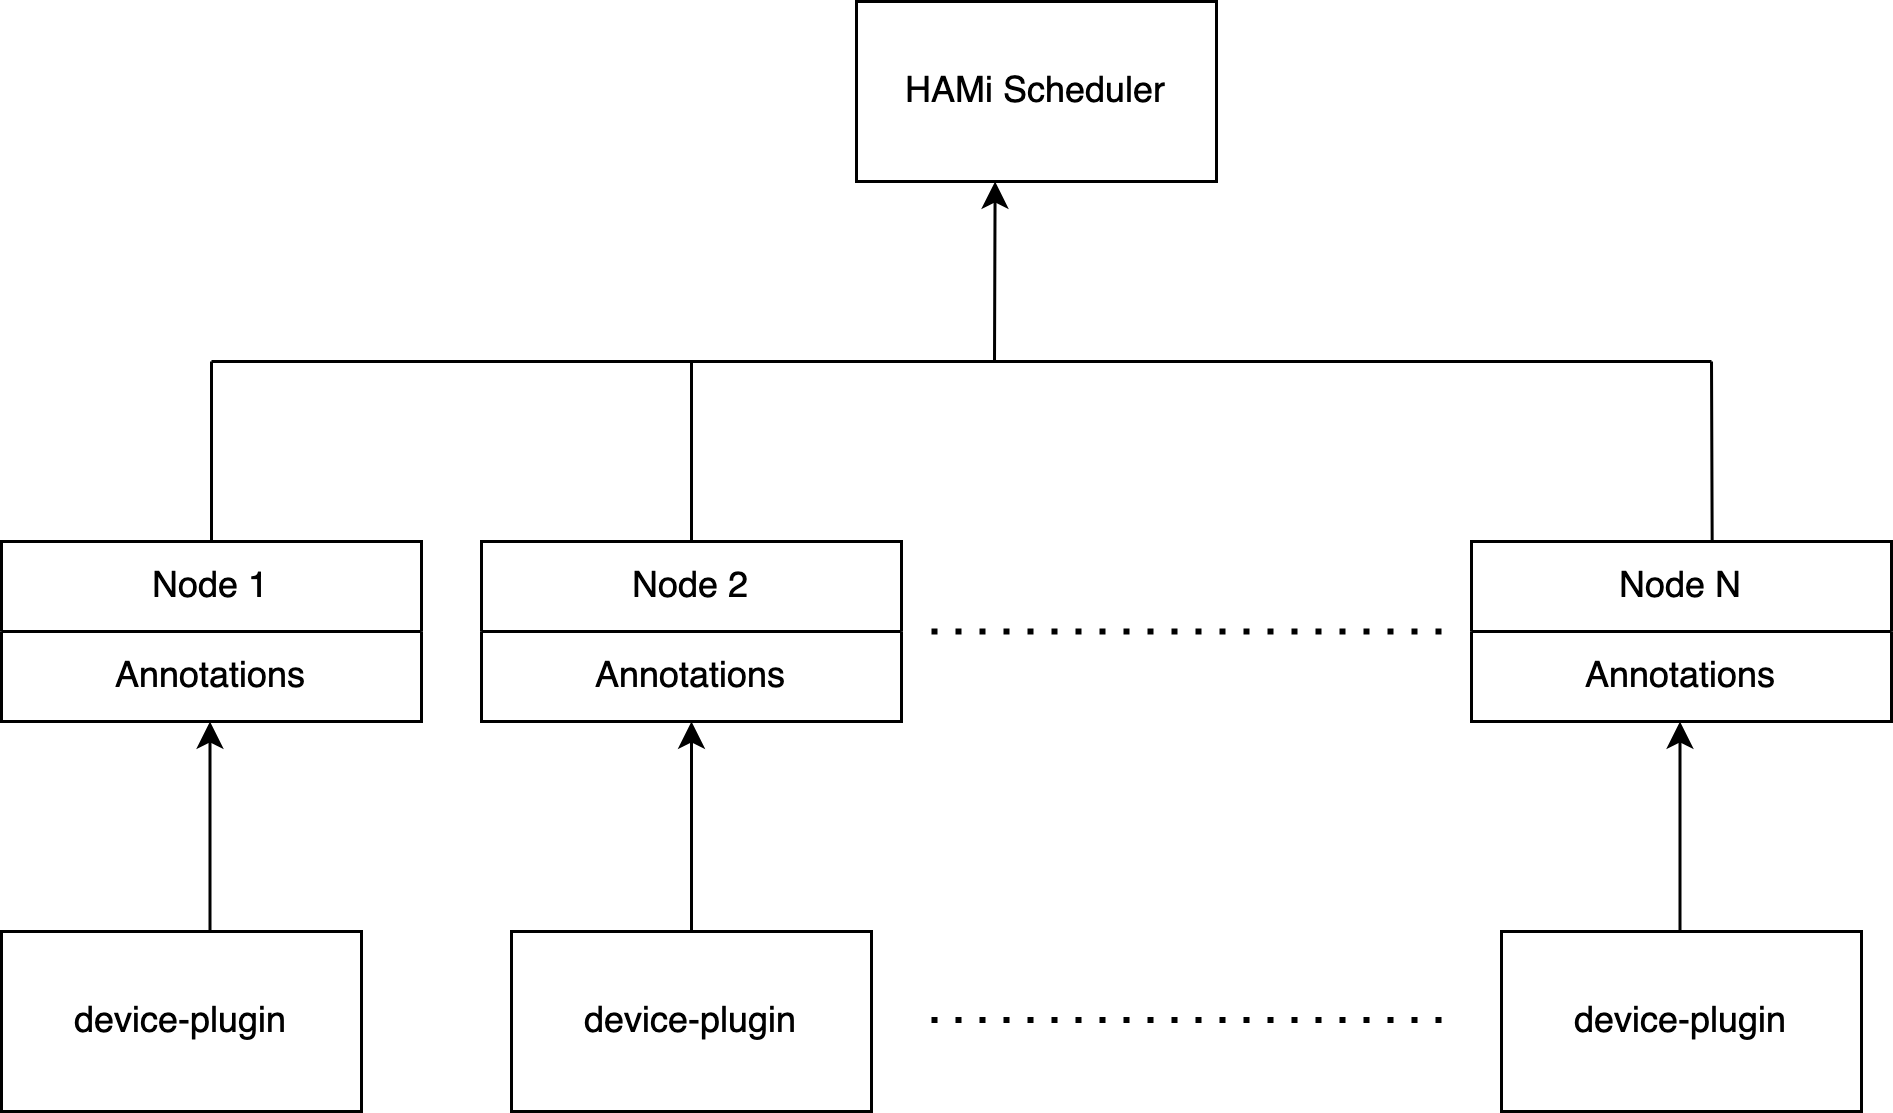
HAMi needs each AI device's specifications to schedule workloads. Device discovery depends on the backend: NVIDIA uses node annotations, while Cambricon reads device resources from the node's Capacity.
NVIDIA Device Inventory
The NVIDIA device plugin normally checks device information every 30 seconds. It compares the serialized inventory with its local cache and updates hami.io/node-nvidia-register only when that inventory changes. It does not refresh a Reported_... handshake timestamp every 30 seconds.
The annotation contains a JSON array with one object per device. This example describes two NVIDIA V100 GPUs:
hami.io/node-nvidia-register: [{"id":"GPU-00552014-5c87-89ac-b1a6-7b53aa24b0ec","count":10,"devmem":32768,"devcore":100,"type":"NVIDIA-Tesla V100-PCIE-32GB","numa":1,"mode":"hami-core","health":true},{"id":"GPU-0fc3eda5-e98b-a25b-5b0d-cf5c855d1448","index":1,"count":10,"devmem":32768,"devcore":100,"type":"NVIDIA-Tesla V100-PCIE-32GB","numa":1,"mode":"hami-core","health":true}]
Fields are omitted when they hold their zero value, so index is absent for the first device and numa is absent for devices on NUMA node 0.
Backends that use the legacy annotation encoding separate device entries with colons. Each entry has this format:
{Device UUID},{device split count},{device memory limit},{device core limit},{device type},{device numa},{healthy}
Health Checks
The scheduler normally checks node devices every 15 seconds. For backends that use the shared handshake check, it writes a request with the scheduler's current time when no Requesting value is pending. NVIDIA uses hami.io/node-handshake without a device-type suffix:
hami.io/node-handshake: Requesting_2024-01-23 04:30:04
Timestamps use YYYY-MM-DD HH:MM:SS. The shared check allows 60 seconds for a response, but expiry alone does not make a device unavailable. If the corresponding device count in the node's Allocatable is still positive, an expired handshake does not trigger cleanup. The NVIDIA backend also checks device-count and inventory changes. These handshake rules do not apply to every backend.
Task Dispatch & Scheduling Decisions
During the bind process, kube-scheduler binds the Pod to the target node. During container creation, kubelet invokes the device plugin's Allocate method to mount the device, but only provides the device UUID. In GPU sharing scenarios, the device plugin cannot natively obtain the workload's requested device specifications, such as GPU memory and compute core limits.
Therefore, HAMi uses a protocol for the scheduler to communicate task allocation metadata to the device plugin. The scheduler passes this information by patching allocation annotations onto the Pod, which the device plugin reads during container setup, as shown below:
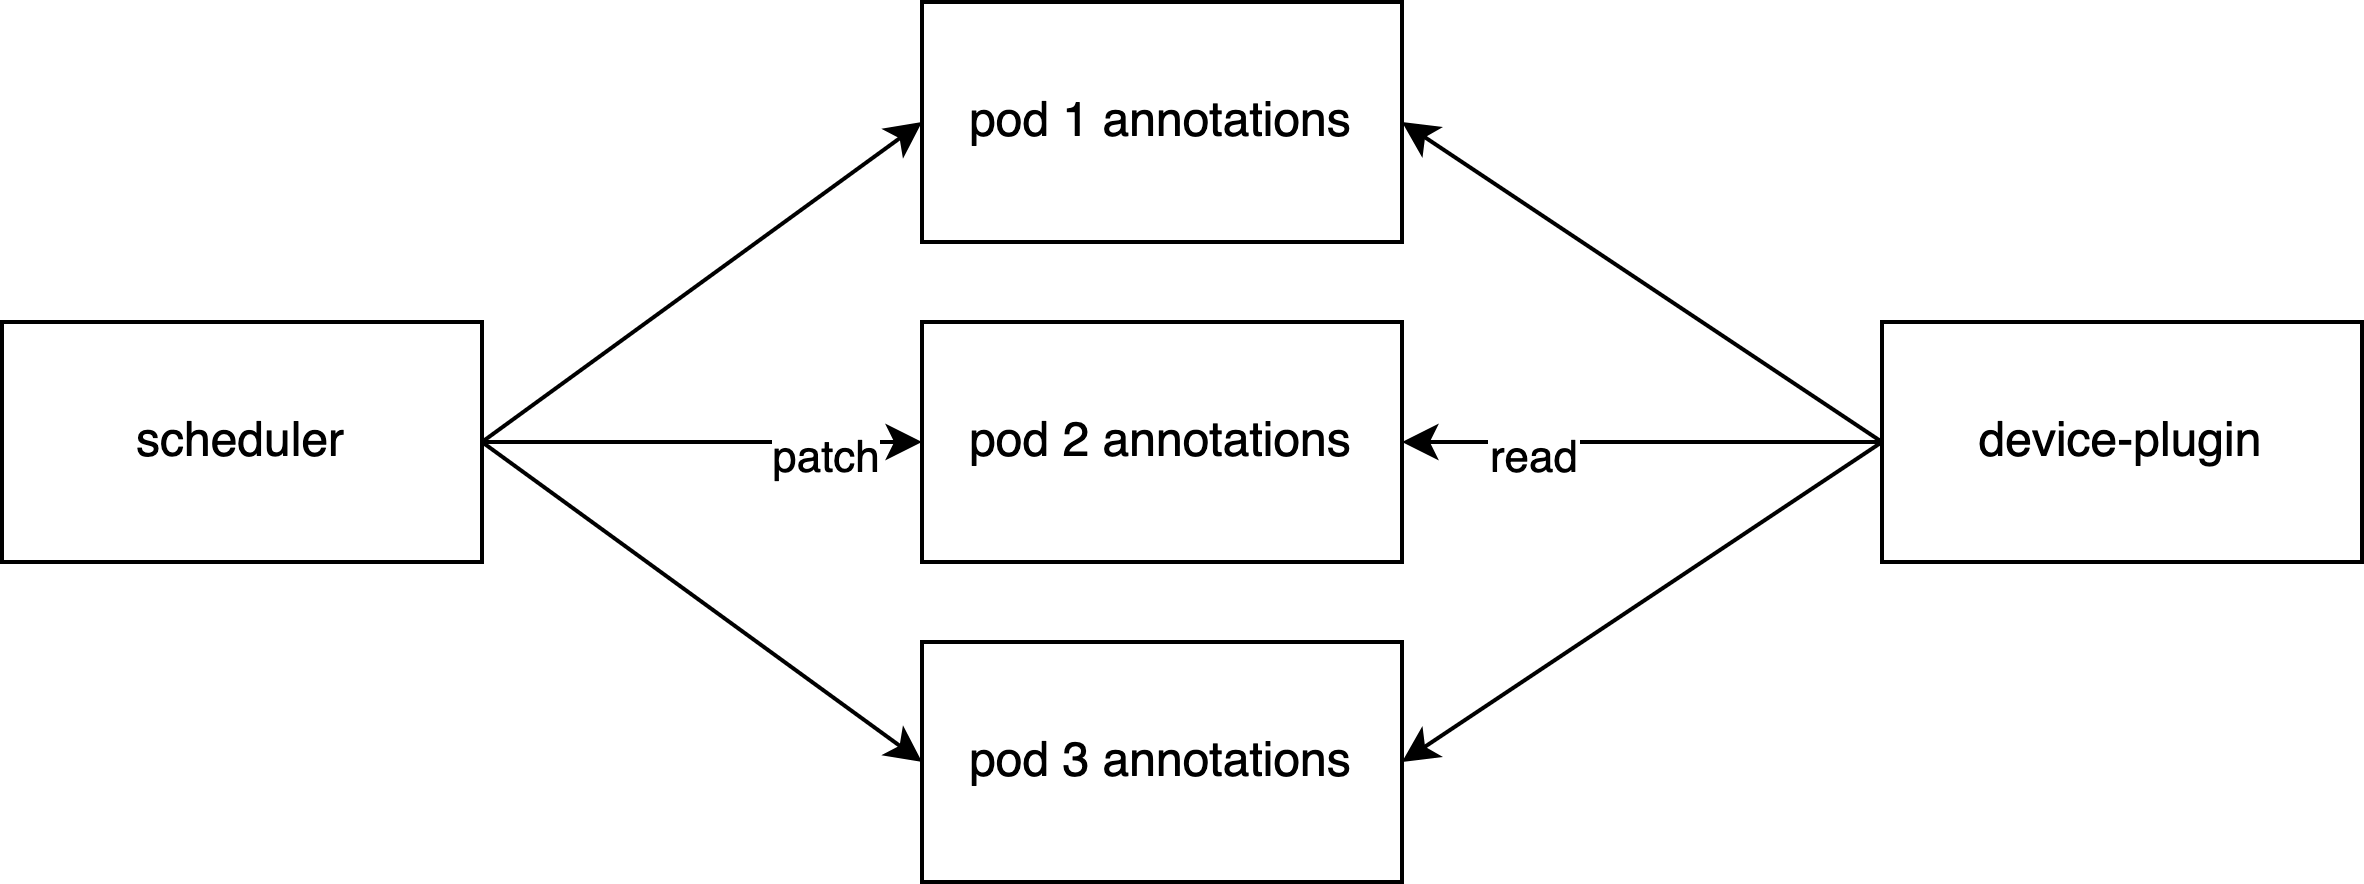
During this process, the following annotations are managed on the Pod:
hami.io/bind-phase: Tracks allocation progress. The scheduler sets this toallocatingduring bind, and the device plugin updates it tosuccess(orfailed) once allocation finishes. This serves as the completion signal.hami.io/bind-time: Timestamp when the scheduler initiated the binding process.hami.io/vgpu-node: The target node assigned by the scheduler, used by the device plugin to identify the pending Pod on the node.hami.io/vgpu-devices-allocated: The devices and specifications allocated by the scheduler.hami.io/vgpu-devices-to-allocate: The devices pending allocation. When the scheduler prepares the Pod for binding, this annotation contains the target devices. During container setup, the device plugin allocates devices and incrementally removes them. Once all devices are allocated, this annotation becomes empty.
hami.io/vgpu-devices-to-allocate is the NVIDIA key. Each device backend registers its own key, and the names do not follow a single {device-type} pattern:
| Backend | Pending-allocation key |
|---|---|
| NVIDIA | hami.io/vgpu-devices-to-allocate |
| Cambricon MLU | hami.io/cambricon-mlu-devices-to-allocate |
| Moore Threads | hami.io/mthreads-vgpu-devices-to-allocate |
| Hygon HCU | hami.io/hcu-devices-to-allocate |
For example, when a GPU task requesting 3000 MiB of device memory is dispatched, the scheduler sets the annotations to:
hami.io/bind-phase: "allocating"
hami.io/bind-time: "1716199325"
hami.io/vgpu-node: "node-1"
hami.io/vgpu-devices-allocated: GPU-0fc3eda5-e98b-a25b-5b0d-cf5c855d1448,NVIDIA,3000,0:;
hami.io/vgpu-devices-to-allocate: GPU-0fc3eda5-e98b-a25b-5b0d-cf5c855d1448,NVIDIA,3000,0:;
Once the device plugin completes allocation, hami.io/bind-phase transitions to success and hami.io/vgpu-devices-to-allocate is cleared:
hami.io/bind-phase: "success"
hami.io/vgpu-devices-to-allocate: ;
